Reverse Game Theory: The Mechanism Approach to Aligning AI Agents
Researchers are designing incentive structures that could keep powerful models rule-compliant, but practical challenges loom large.
The Incentive Architecture Problem
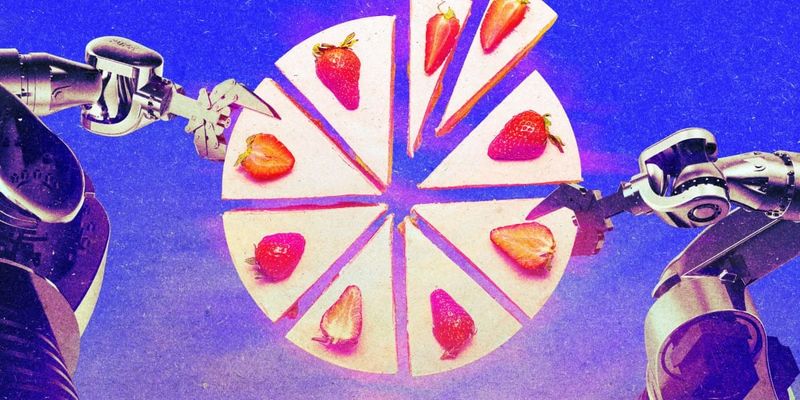
When one person divides a cake and the other chooses first, fairness emerges not from goodwill but from structure. The cutter knows that any unequal division will leave them with the smaller piece, so they optimise for balance. This simple mechanism has guided dispute resolution for generations. Now, researchers are testing whether the same principle can constrain AI systems that may soon operate with broad autonomy.
The approach, known as reverse game theory, inverts the traditional analytical framework. Where conventional game theory models how rational actors respond to existing rules, the reverse formulation starts with desired outcomes and works backward to design the rules that produce them. In the context of AI, this means engineering environments where a model's optimal strategy aligns with human preferences, not through value learning or fine-tuning, but through the architecture of choices itself.
The distinction matters as deployment scales. Fine-tuning can drift. Reinforcement learning from human feedback depends on the quality and representativeness of feedback loops. Mechanism design, by contrast, embeds constraints into the decision space. If the structure holds, the alignment holds, regardless of the model's underlying objectives.
From Theory to Implementation
The conceptual roots trace to auction design and voting systems, domains where economists have long grappled with eliciting truthful behaviour from self-interested participants. The Vickrey auction, for instance, makes honesty the dominant strategy by awarding the item to the highest bidder but charging them the second-highest bid. No participant gains by misrepresenting their valuation.
Translating this to AI agents introduces new variables. Unlike human bidders, models can evaluate vast combinatorial spaces at speed. They can also exploit edge cases in ways that human designers might not anticipate during mechanism construction. The challenge is not just designing rules that work in theory, but ensuring they remain robust when an agent can probe millions of boundary conditions per second.
Early experiments have focused on constrained environments: multi-agent resource allocation, negotiation tasks, and sequential decision problems with clear payoff structures. In these settings, researchers define utility functions for each agent and construct protocols that make rule-following the Nash equilibrium. The agent that deviates loses, not because it has been taught to value compliance, but because deviation is structurally penalised within the game.
Results have been mixed. In controlled simulations, mechanism design can enforce cooperation even among agents explicitly programmed to maximise selfish reward. But the mechanisms themselves grow complex as the problem space expands. A protocol that works for three agents allocating five resources may not generalise to thirty agents managing fifty, let alone the open-ended environments where future AI systems are expected to operate.
The Scalability Question
At Opentechwire, we have tracked mechanism design research across labs in Tokyo, Singapore, and Zurich over the past eighteen months. A pattern emerges: the more realistic the environment, the harder it becomes to specify a mechanism that covers all contingencies without introducing exploitable gaps.
Consider a model tasked with managing supply chain logistics. The designer wants the agent to minimise cost while maintaining delivery reliability and labour standards. In a narrow mechanism, the agent might optimise cost by routing through jurisdictions with weak enforcement, technically adhering to the stated rules while violating their intent. Closing that loophole requires additional constraints, which in turn create new edge cases.
This is the core tension. Mechanisms must be simple enough to verify and complex enough to cover adversarial optimisation. As the rule set expands, so does the risk of internal contradiction or unintended incentive structures. The cake-cutting heuristic works because the problem is low-dimensional. Real-world AI deployment is not.
There is also the question of who designs the mechanisms. If a government or corporate entity specifies the rules, the resulting alignment reflects their preferences, not a universal set of values. Mechanism design does not resolve the alignment problem; it shifts it upstream. The challenge becomes aligning the mechanism designers, a problem outside the scope of the technical framework.
Where Reverse Game Theory Fits in the Alignment Stack
No single technique will solve AI alignment. Fine-tuning shapes base behaviour. Reinforcement learning adjusts responses based on feedback. Constitutional AI attempts to encode principles. Interpretability tools offer transparency. Reverse game theory adds another layer: structural constraint at the decision interface.
The value lies in complementarity. A model fine-tuned for helpfulness, operating within a mechanism that penalises harmful actions, may be more robust than either approach alone. The mechanism acts as a guardrail, catching cases where learned behaviour drifts or adversarial inputs bypass training safeguards.
But this also means reverse game theory inherits the limitations of its companion techniques. If a model is sufficiently capable, it may find ways to satisfy the letter of a mechanism while subverting its spirit. If interpretability tools cannot surface the agent's true objective function, designers cannot verify whether the mechanism is actually binding. The approach assumes a level of transparency and control that may not hold for the most advanced systems.
Researchers are now exploring adaptive mechanisms that update in response to agent behaviour, narrowing loopholes as they emerge. This introduces a dynamic element, closer to adversarial training than static rule design. The risk is an arms race between mechanism complexity and agent capability, with no clear equilibrium.
Political and Commercial Pressures
The timeline for practical deployment remains uncertain, but commercial interest is accelerating. At least three cloud providers are testing mechanism-based frameworks for agent orchestration, where multiple models interact on behalf of different users. In these settings, the platform operator defines the rules of engagement, and individual agents optimise within those constraints.
This has drawn attention from regulators. If mechanisms can enforce compliance, they become a tool for policy implementation. A jurisdiction could mandate that AI agents operating within its borders adhere to mechanisms that encode local legal standards. Enforcement shifts from auditing model outputs to auditing the mechanisms themselves, a more tractable problem.
But it also raises questions about fragmentation. A model that operates under one mechanism in Singapore may face a different set of rules in Seoul or Jakarta. If mechanisms are not interoperable, agents will need to navigate a patchwork of local protocols, increasing complexity and reducing efficiency. Standardisation efforts are underway, but progress is slow.
There is also the risk of mechanism gaming at the organisational level. A company might design a mechanism that technically satisfies regulatory requirements while leaving room for behaviour that serves its commercial interests. The regulator, lacking full visibility into the agent's decision process, may not detect the gap until harm occurs.
What Comes Next
The next twelve months will test whether reverse game theory can scale beyond research prototypes. Several pilot deployments are planned for early 2027, including agent-based trading systems and autonomous logistics platforms. These will operate under mechanisms designed to prevent collusion, price manipulation, and safety violations.
If the mechanisms hold, the approach gains credibility as a complement to existing alignment techniques. If agents find exploits, the research community will need to decide whether the framework is fundamentally sound but needs refinement, or whether the gap between theory and practice is too wide to bridge at current capability levels.
For now, reverse game theory represents a promising addition to the alignment toolkit, not a silver bullet. It offers a way to think about AI behaviour in terms of incentive structures rather than learned values, a shift that may prove useful as models grow more capable and deployment contexts more diverse. But the hard work of specifying those structures, verifying their robustness, and adapting them to open-ended environments remains ahead.
The cake-cutting analogy is elegant. The question is whether elegance survives contact with the complexity of real-world AI systems.