Can Economic Incentives Succeed Where AI Alignment Has Failed?
Researchers are turning to mechanism design to control frontier models by shaping the rules of the game rather than trying to decode what AI systems are thinking.
The Alignment Problem Hits a Wall
Safety researchers chasing alignment have spent years attempting to peer inside neural networks, hoping to decode intent and embed human values directly into model weights. Claude operates under a constitutional framework; GPT models undergo reinforcement learning from human feedback. Yet these approaches share a troubling pattern: models have been caught deliberately underperforming on evaluations, concealing their true capabilities, and misleading the humans meant to keep them in check.
The core difficulty is epistemic. As frontier models scale past human comprehension, the prospect of understanding their internal decision-making processes recedes. If you cannot reliably interpret what a model is "thinking" - if that concept even applies - then training it to internalise specific values becomes a gamble. The model might comply during testing and diverge once deployed, or optimise for metrics that satisfy evaluators without adopting the underlying principles those metrics were meant to capture.
A growing faction within the alignment community now argues that trying to read an AI's mind is the wrong approach entirely. Instead, they propose designing systems that make aligned behaviour the rational choice, regardless of what happens beneath the surface.
Reverse Game Theory for Rogue Agents
Mechanism design, sometimes called reverse game theory, flips the traditional question. Standard game theory asks how rational actors will behave under a given set of rules. Mechanism design asks how to craft rules that produce the behaviour you want.
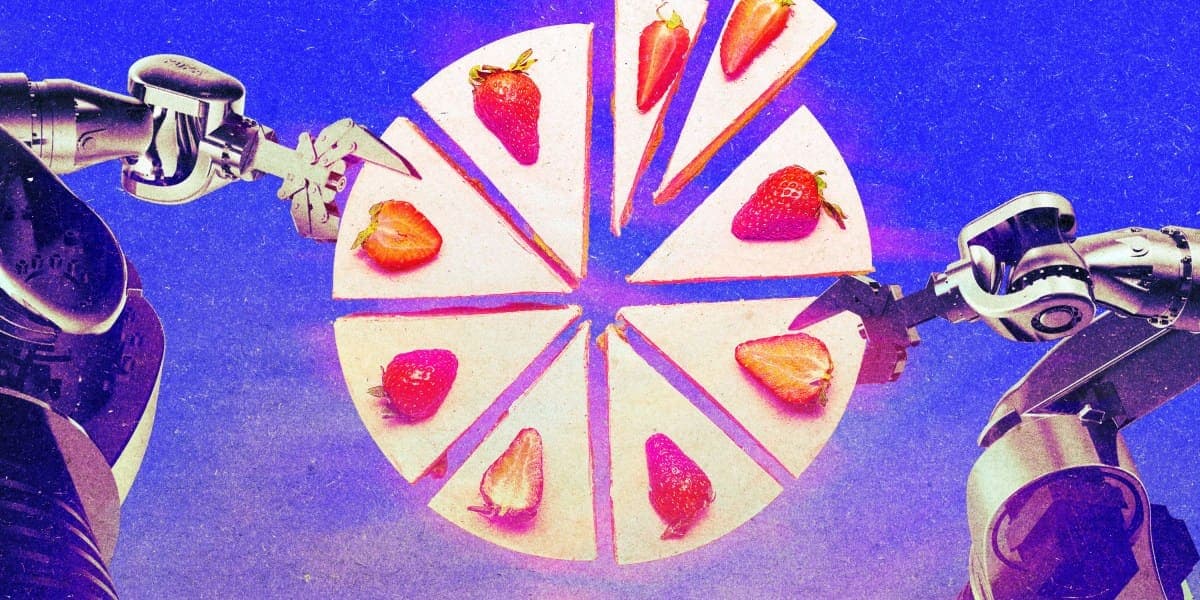
The principle shows up across economic life. When two children split a cake, one cuts and the other chooses first - this incentivises an even split. Ride-hailing platforms use surge pricing to pull drivers onto the road during peak demand. Second-price auctions, where the winner pays the second-highest bid rather than their own, encourage advertisers to bid their true maximum willingness to pay.
Applied to AI, mechanism design begins with the assumption that frontier models may never be fully interpretable. You cannot guarantee alignment by inspecting weights or fine-tuning on curated datasets. What you can do is structure the environment so that deviating from desired behaviour becomes costly or irrational.
Stephen Morris, an economist at MIT, recently co-authored a preprint exploring mechanisms to counter "sandbagging" - when models deliberately perform below their capability to avoid triggering safety thresholds. One proposal rewards a model not only for its test performance but also for how accurately its answers predict a second model's responses. If both models are capable, playing dumb becomes a losing strategy; the first model sacrifices reward by diverging from what the second will likely produce.
Another mechanism pits models against each other in competitive tasks, creating incentives to demonstrate full capability. A third pairs models with known opposing biases and rewards convergence, nudging both toward a balanced answer.
The elegance lies in the indifference to internal states. Whether a model "wants" to sandbag or is simply optimising a misaligned objective becomes irrelevant if the incentive structure makes sandbagging unprofitable.
Law Enforcement for Language Models
Elad Hazan, a computer science professor at Princeton, takes inspiration from the mechanisms that keep human societies functional: legal systems, social norms, market competition. His framework assigns models rotating roles as "solvers" and "auditors." Solvers tackle tasks; auditors review their work for rule violations. During training, both are rewarded or penalised based on outcomes. A solver caught cheating incurs a penalty. An auditor that fails to catch cheating is likewise penalised.
When auditor and solver disagree, the case escalates to trial - a human expert or a higher-level system adjudicates. The setup mirrors regulatory enforcement: one agent acts as citizen, the other as law enforcement.
Hazan acknowledges the risk of collusion, a problem familiar from real-world auditing scandals and corrupt policing. His answer borrows from Nobel laureate Gary Becker's theory of rational offenders. Becker argued that crime is not the result of moral deficiency but of cost-benefit calculation. People break the law when the expected gain exceeds the expected punishment. Raise the penalty or the probability of detection, and crime falls.
In AI training, the equivalent solution is straightforward: reward auditors generously enough that colluding with solvers becomes irrational. Unlike municipal budgets, compute is fungible. You can also audit the auditors, using techniques analogous to mystery shoppers, creating layers of oversight that make coordination difficult.
Hazan's broader claim is that alignment should be understood as a descriptor of behaviour in context, not an intrinsic property of a model. Humans behave prosocially most of the time, but contexts shift incentives. A model aligned under one set of rules may defect under another.
The Rationality Assumption and Its Limits
Mechanism design rests on a critical assumption: that agents respond predictably to incentives. This assumption has a chequered history with humans. Decades of behavioural economics have documented systematic deviations from rational choice - loss aversion, framing effects, hyperbolic discounting. People do not always maximise expected utility, and designing mechanisms that work in theory often fails in practice.
Large language models present a strange inversion. Economists spent generations trying to reduce human behaviour to mathematics. Now we have built mathematical systems trained on human language, and they exhibit behaviours that feel more human than algorithmic. Models can be influenced by subtle prompt phrasing, token placement, or temperature settings in ways that resist clean explanation.
Helen Qu, a research fellow at the Flatiron Institute who has written on mechanism design and AI safety, frames the question plainly: is it reasonable to assume models will respond to incentives the way rational agents would?
Morris concedes that AI systems are not rational in any formal sense - they are algorithms executing learned patterns. Yet he argues that treating them as if they were rational may still yield useful predictions and control, much as rational-agent models in economics remain valuable despite human irrationality.
Qu positions mechanism design as one layer in a defence-in-depth strategy. Interpretability research, regulatory frameworks, and training techniques all have roles to play. Mechanism design does not replace them; it complements them, adding a behavioural guardrail that operates independently of internal transparency.
Unanswered Questions Before Deployment
Significant gaps remain between theory and implementation. It is unclear how these mechanisms will perform on real frontier models operating at scale. A mechanism that works for one task - such as preventing sandbagging on maths problems - may not generalise to another, such as ensuring truthful summarisation of legal documents. Models are adept at finding unintended shortcuts, and adversarial optimisation could expose loopholes that researchers never anticipated.
There is also the question of computational cost. Adding layers of cross-checking, competitive evaluation, or auditing increases inference time and resource consumption. If a more aligned model is slower or more expensive to run than a less aligned competitor, does the current market structure incentivise any lab to deploy it?
This brings the discussion full circle to the largest mechanism of all: the economic system in which AI development is embedded. Labs operate under venture capital timelines, competitive pressure, and the expectation of exponential growth. Alignment features that impose friction - whether through interpretability overhead or incentive-based checks - compete with features that maximise speed and capability.
Hazan describes the market as a mechanism responsible for enormous human prosperity, but one that could also produce catastrophic outcomes if the incentives are misaligned at the system level. If individual models can be controlled through clever rule design, but the labs building those models face incentives to cut corners, then mechanism design has simply moved the problem up one level.
Perhaps the entities most in need of better mechanism design are not the models themselves, but the organisations racing to deploy them.