Beijing Bets on State Giant to Break China's Data Deadlock
A new centrally managed enterprise in Xiongan aims to unlock siloed information for AI training, but institutional barriers run deep
A Centralised Play in a Fragmented Landscape
On 20 October, China established a centralised state-owned enterprise tasked with a singular mission: turning the country's sprawling digital holdings into training material for artificial intelligence. Headquartered in Xiongan New Area, Hebei province, the national data group operates under direct central government oversight, a structure that reflects how seriously policymakers view the bottleneck.
The timing is deliberate. Chinese AI labs are scaling foundation models at a pace that demands exponentially larger, cleaner datasets. Yet much of the country's most valuable information sits locked inside provincial archives, state ministries, utility operators, and private platforms, each governed by distinct access rules and reluctant to share. At Opentechwire, we have tracked dozens of provincial data exchanges over the past three years; the majority handle fewer than a dozen transactions annually, often within a single sector. The new entity is designed to override that inertia.
Why Data Remains Siloed
China generates more digital exhaust than almost any nation. E-commerce logs, ride-hailing trajectories, health records, industrial sensor feeds, and surveillance footage collectively represent petabytes of structured and unstructured information. In principle, pooling even a fraction of these streams would give domestic AI developers a training advantage. In practice, the data remains fragmented.
Three forces sustain the silos. First, government departments treat datasets as administrative assets, reluctant to expose them for fear of revealing inefficiencies or enabling audit scrutiny. Second, provincial and municipal authorities compete for investment and revenue; sharing datasets can mean ceding an edge to a neighbouring jurisdiction. Third, state-owned enterprises in energy, telecoms, and transport view proprietary operational data as competitive moats, even when the competition is notional.
Existing regulations compound the problem. China's 2021 Data Security Law and 2021 Personal Information Protection Law impose tiered classification and consent requirements, but offer little clarity on how public entities should handle inter-agency transfers or commercial licensing. The result is a default posture of caution: when in doubt, do not share.
The Xiongan Model
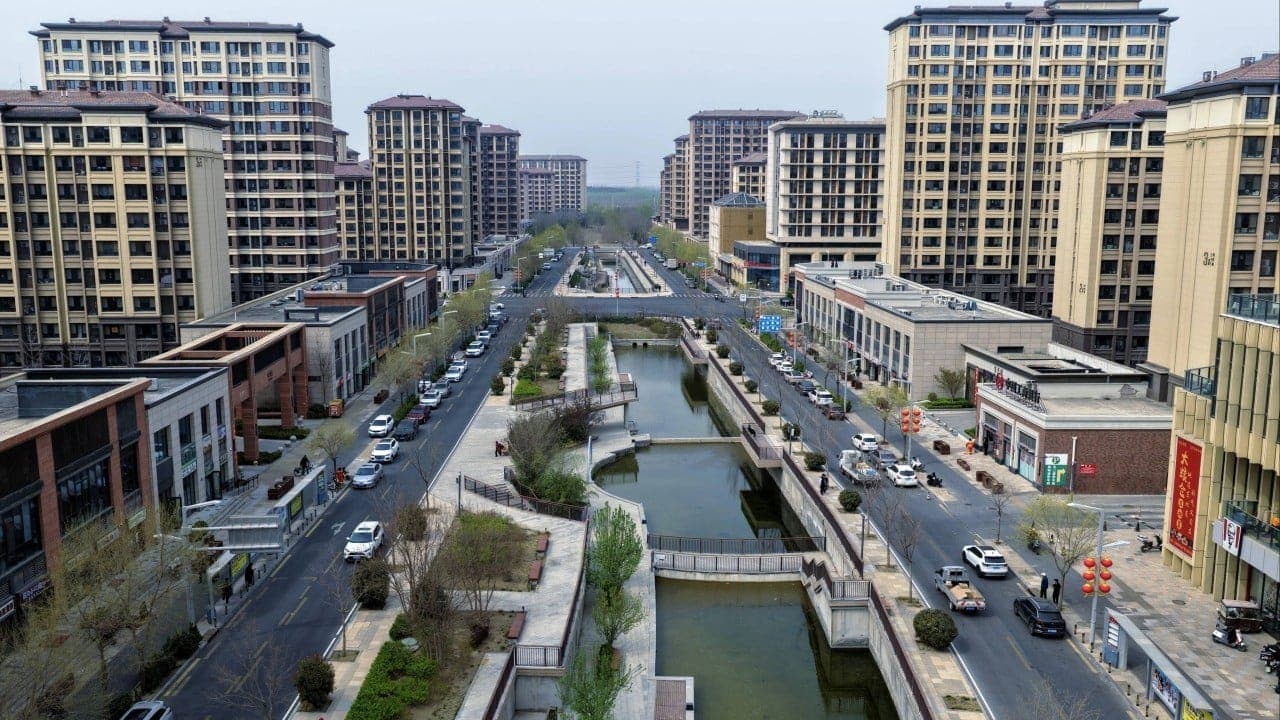
The choice of Xiongan is symbolic and logistical. Designated in 2017 as a "millennium project" to relieve pressure on Beijing, the new area has served as a testbed for smart-city infrastructure, blockchain-based land registries, and digital twin simulations. Embedding the national data group there signals that the initiative is not simply another coordinating committee but a permanent operational hub with its own technical stack.
Structuring the group as a central state-owned enterprise grants it authority that provincial data exchanges lack. In China's administrative hierarchy, centrally managed SOEs report directly to the State-owned Assets Supervision and Administration Commission and, by extension, the State Council. That elevates the group above the parochial interests of local governments and gives it the bureaucratic heft to demand datasets from ministries and state firms.
Yet authority alone will not dissolve institutional resistance. The group will need to offer something in return: standardised anonymisation pipelines, revenue-sharing frameworks, or liability shields that reassure data custodians they will not be penalised for breaches downstream. None of these mechanisms exist in mature form today.
What AI Labs Need
Foundation models trained on web scrapes and public corpora are hitting performance plateaus. The next leap requires domain-specific, high-fidelity datasets: radiology images labelled by specialists, factory maintenance logs annotated with failure modes, traffic patterns tagged with weather and incident metadata. These are precisely the datasets that sit inside hospitals, manufacturers, and municipal transport bureaus, often in formats that require significant curation before they become training-ready.
Chinese AI companies have spent the past two years negotiating one-off partnerships with individual data holders, a process that is slow, expensive, and non-repeatable. A centralised group that can aggregate, clean, and license datasets under uniform terms would accelerate model iteration and lower the cost of experimentation. For smaller labs without the resources to strike bespoke deals, access to such a catalogue could be transformative.
The demand is not hypothetical. Firms building medical imaging models, autonomous driving stacks, and industrial predictive maintenance systems have publicly cited data scarcity as a binding constraint. The national data group, if it can deliver volume and variety, addresses a real bottleneck.
Risks and Unknowns
Centralisation creates its own hazards. Concentrating sensitive datasets in a single entity magnifies the consequences of a security breach or misuse. The group will inherit the combined cyber-attack surface of every contributing organisation, and state-sponsored adversaries have demonstrated sustained interest in Chinese government databases.
There is also the question of commercial neutrality. If the group prioritises certain AI labs or sectors, it risks distorting competition and entrenching incumbents. Transparent pricing and access criteria will be essential, yet Chinese SOEs have historically struggled with both. The lack of independent oversight mechanisms compounds the risk of favouritism.
Finally, the venture assumes that more data automatically yields better models. In reality, model performance depends on data quality, diversity, and alignment with the task at hand. A poorly curated national dataset, bloated with redundant or mislabelled examples, could waste compute resources and produce brittle models. The group will need deep technical expertise in data engineering, not just administrative clout.
Regional Precedent and Pressure
China is not alone in attempting to mobilise national datasets for AI. The European Union's Data Governance Act establishes frameworks for data intermediaries and cross-border sharing, though implementation remains patchy. South Korea's Data Industry Promotion Act, enacted in 2021, created incentives for public-private data collaboration, with mixed results. Japan's quasi-public data banks, launched in 2020, have facilitated healthcare and transport projects but remain limited in scope.
What distinguishes the Chinese approach is scale and centralisation. The Xiongan group is not a voluntary consortium or a regulatory framework but a state-owned operator with the mandate and capital to acquire, standardise, and redistribute datasets. Whether that model proves more effective than decentralised, market-driven alternatives will depend on execution.
The Path Ahead
The national data group's success will be measured not by the volume of data it amasses but by the number of AI applications it enables. If Chinese labs can train more accurate diagnostic models, more efficient logistics algorithms, or more capable natural language interfaces because of access to the group's catalogue, the initiative will have justified its existence. If the group becomes a bureaucratic gatekeeper that slows innovation or favours connected insiders, it will join the long list of state-led digital initiatives that faltered in implementation.
Early indicators will include the speed at which provincial governments and central ministries begin contributing datasets, the clarity of licensing terms, and the diversity of organisations granted access. At Opentechwire, we will be watching whether the group publishes a public catalogue, adopts open standards for metadata, and establishes an appeals process for denied access requests. These details, more than grand announcements, will reveal whether Beijing's latest data venture can overcome the inertia that has stalled previous efforts.
The stakes extend beyond AI. If the group can demonstrate a workable model for pooling and licensing public-sector data, it may serve as a template for other domains, from climate modelling to urban planning. But first, it must prove that a state-owned giant can succeed where markets and coordination have so far failed.