Why One Silicon Valley CEO Pays Six Figures a Year for AI Agents
Garry Tan's personal token bill reveals the cost barrier keeping autonomous AI assistants out of reach for most users, even as the technology reshapes how work gets done.
A Six-Figure Habit
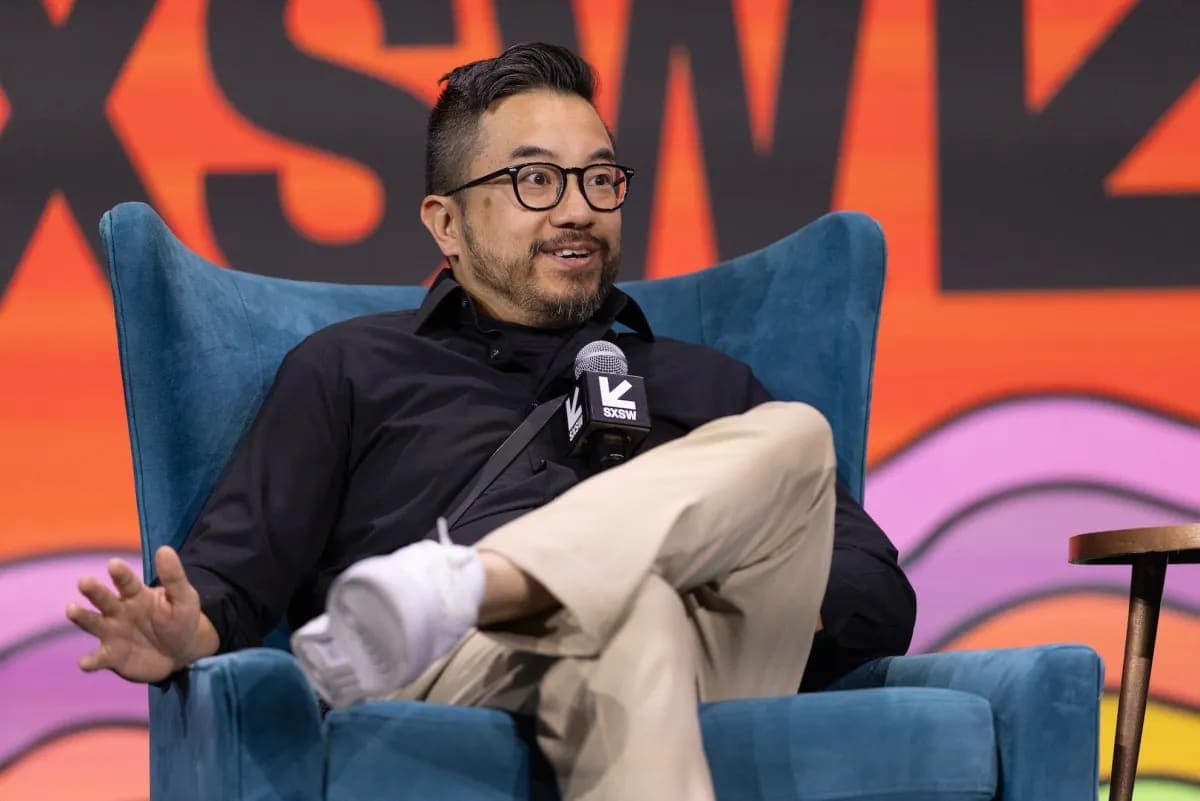
Garry Tan shells out between 100,000 and 200,000 USD each year on API tokens to power the AI agents that have become integral to how he works and lives. The chief executive of Y Combinator shared the figure during a conversation on Walter Isaacson's podcast The Builders, quantifying what may be the most expensive personal AI habit in Silicon Valley.
The spending supports a sprawling ecosystem of autonomous tools. Tan uses agents for research, coding tasks, and operational work across the accelerator's portfolio. One agent has ingested two decades of his personal archives, including email, cloud storage, notes, and therapy records. Another, named Stray Light, functions as an institutional memory system for Y Combinator itself, holding context on every founder the programme has backed, every application it has received, and every inbound message to the organisation.
Tan has published a collection of 23 Claude agent configurations on GitHub under the name gstack, positioning the release as an educational resource for developers exploring what autonomous systems can accomplish. The toolkit reflects his view that agents should operate less like deterministic software and more like collaborators capable of anticipation and initiative.
How the Tools Work
The agents Tan relies on span a wide functional range. At the simpler end, he deploys them for interview preparation, the kind of task many users now handle with conversational AI. At the complex end, they act as what he calls a constant companion, able to suggest next steps, surface relevant context, and handle tasks with minimal prompting.
He describes the experience as having assistance available for nearly any aspect of daily life, operating with enough autonomy to move ahead of explicit instructions. The agents draw on comprehensive personal data to tailor their responses, a level of integration that requires both technical infrastructure and comfort with exposing large volumes of private information to language models.
Y Combinator has embedded agent-driven workflows into its internal operations. Stray Light, the institutional agent Tan referenced, is described as possessing a personality alongside its database of organisational knowledge. The system is being used to rethink processes at the accelerator, though Tan did not detail specific workflows or efficiency gains in his remarks.
The Cost Problem
Tan acknowledged that his token expenditure represents a privilege inaccessible to the vast majority of potential users. He sees cost as the primary obstacle preventing personal AI agents from achieving mainstream adoption. Current pricing models, which charge per token consumed during inference, make sustained use of powerful agents prohibitively expensive for individuals and small teams operating outside venture-backed environments.
The economics present a strategic tension. Inference costs have declined as model providers scale infrastructure and optimise serving, but the kind of deep, stateful, context-rich interactions Tan describes still require moving large volumes of data through expensive frontier models. For agents to reach ubiquity, either model efficiency must improve by orders of magnitude or pricing structures must shift away from per-token billing.
At Opentechwire, we have tracked the widening gap between early adopter use cases and mass-market viability across AI product categories. Agent costs mirror the pattern seen in fine-tuning and embedding-heavy applications: power users extract enormous value, but the price floor remains too high for casual adoption. Unlike previous waves of software, where marginal cost per user approached zero, language model inference retains a hard cost floor tied to compute.
Platform Control and the Free-Agent Dilemma
Tan raised a second concern alongside cost: control. He pointed to Meta's algorithmic influence over social media feeds as an example of centralised platform power that users tolerate but resent. Free or subsidised AI agents offered by large technology companies risk replicating that dynamic, where the entity providing the service retains ultimate authority over how the agent behaves, what it prioritises, and what data it collects.
The alternative Tan sketched involves personal agents that users can programme and direct themselves, free from the incentive structures of advertising-supported platforms. That vision aligns with open-weight models and local inference, but both approaches currently demand technical expertise and hardware investment that push them out of reach for non-specialist users.
The tension between cost and control is not new to consumer technology. Subsidised services funded by attention or data collection have historically won market share over paid alternatives that offer greater user autonomy. Whether AI agents follow the same trajectory depends on how much users value privacy and customisation versus convenience and zero upfront cost.
What Tan Learned from Heavy Use
Tan's experience as an early and intensive user has shaped his view of how agents should be built and deployed. He cautioned against treating them as traditional software, where repeatability and deterministic behaviour are paramount. That mindset, he argued, sacrifices the adaptability and human-like responsiveness that make agents useful in the first place.
The comment reflects a broader design debate in the AI product community. Safety-conscious engineering practices emphasise constrained outputs, validation steps, and rollback mechanisms to prevent agents from taking unintended actions. Tan's argument is that excessive caution strips away the autonomy that defines an agent, reducing it to a scripted assistant.
His approach, which involves granting agents access to sensitive personal data and allowing them to operate with minimal oversight, is unlikely to generalise to enterprise or regulated environments. But it demonstrates the ceiling of what current agent frameworks can achieve when cost and risk tolerance are not constraints.
Institutional Memory at Scale
The deployment of Stray Light inside Y Combinator offers a glimpse of how organisations might use agents to encode and surface institutional knowledge. The accelerator evaluates thousands of applications each batch, maintains relationships with thousands of alumni companies, and fields a constant stream of inbound requests. Centralising that context in a queryable, conversational interface could compress the onboarding time for new partners and reduce the cognitive load of tracking portfolio developments.
Similar systems are being tested at venture firms and professional services organisations across the region. The challenge is ensuring the agent's outputs remain accurate and up-to-date as the underlying data evolves. Language models are prone to hallucination, and the consequences of an agent confidently delivering incorrect information about a founder or deal term are higher in a professional setting than in personal use.
Tan did not specify which model or inference provider powers Stray Light, nor did he address how Y Combinator handles data governance for an agent with access to confidential applicant and founder information. Those details will matter as more organisations consider similar deployments.
The Path to Ubiquity
For personal AI agents to move beyond the early-adopter tier, two shifts are necessary. First, inference costs must drop by at least an order of magnitude, either through model efficiency improvements or structural changes in how providers price long-running, stateful sessions. Second, user interfaces must abstract away the complexity Tan currently navigates through GitHub repositories and custom configurations.
The companies best positioned to deliver both are the frontier model providers, the hyperscalers with inference infrastructure, and a cohort of agent-platform start-ups emerging from accelerators including Y Combinator itself. Each faces trade-offs. Model providers want to maximise revenue per token. Hyperscalers want to lock users into their clouds. Start-ups want to own the user relationship but lack the capital to subsidise compute.
Tan's spending offers a data point for how much value a sophisticated user can extract from agents at current capability levels. Whether that value can be delivered at a price the broader market will pay remains the open question.