Meta Pushes Into Frontier AI With Muse Wonder Release
The Superintelligence Lab's new models target GPT-6 and Fable 5.1, pricing at $4/$20 per million tokens while emphasising long-term memory over raw benchmarks.
Meta's Belated Entry Into the Frontier Race
Meta's Superintelligence Lab shipped Muse Wonder and Muse Wonder Full on Monday, the company's first attempt at competing directly with OpenAI's GPT-6 series and Anthropic's Fable line. The two models mark a departure from the lightweight Muse Spark released earlier this year, which prioritised low latency over capability. Wonder targets complex reasoning and extended coding tasks, with benchmark performance that Meta claims sits alongside GPT-6 Astra and Fable 5.1.
The pricing reflects that ambition. Accessed through the Meta Model API, Wonder will cost $4 per million input tokens and $20 per million output, roughly matching GPT-6 Sol and Opus 5.5. Wonder Full, meanwhile, will be exclusive to Muse Code subscribers and will not be served through the API at all. Both models will also power the Muse agent, Meta's long-running effort to build assistants capable of multi-day workflows.
At Opentechwire, we have tracked Meta's AI strategy since Alexandr Wang, founder of Scale AI, restructured the division in August of last year. Until now, Meta's post-restructure releases have been either lightweight inference models or agentic interfaces, avoiding the kind of headline-grabbing frontier launches that define OpenAI and Anthropic's cadence. Wonder represents a shift in that posture.
Memory as the Differentiator
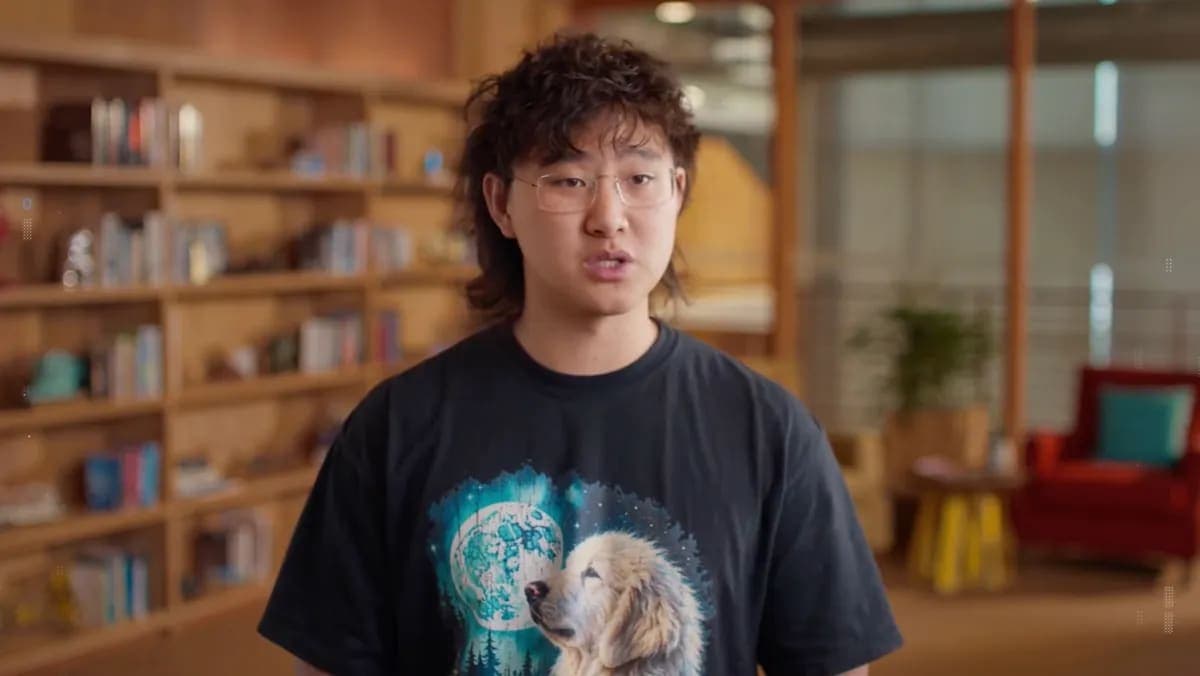
Where GPT-6 and Fable have competed largely on reasoning benchmarks and coding accuracy, Meta is positioning Wonder around what it calls "active memory", the ability to retain and synthesise user context over days, weeks, or months. Research scientist Kavya Kopparapu emphasised this in a video accompanying the launch, noting that the team invested heavily in ensuring the model can recall information across extended sessions.
To validate that claim, Meta highlighted performance on MemoryBench, a benchmark designed to test continual learning and memory construction. According to the company's internal testing, Muse Wonder now outperforms Fable, Opus, and Astra on MemoryBench, though the company did not release absolute scores or methodology details.
This focus on memory aligns with Meta's broader thesis that personal AI assistants will succeed or fail based on their ability to maintain context over long arcs of interaction, not just within a single session. That thesis has shaped the Muse agent's design since its inception, and Wonder is the first model explicitly engineered to support it at the frontier scale.
Training Infrastructure and the Ohio Data Centre
Meta trained both Wonder models at its Prometheus data centre in central Ohio, which came online earlier this year. The facility represents a significant capital commitment; while Meta has not disclosed the exact training cost for Wonder, frontier models of this class typically require compute budgets in the tens of millions of dollars and training runs spanning weeks or months.
The Ohio location is part of a broader pattern among hyperscalers to site AI infrastructure in the US Midwest, where land, power, and cooling are cheaper than coastal markets. For Meta, Prometheus also provides a hedge against the supply chain volatility that has plagued GPU procurement since 2024. By controlling the data centre stack, Meta can prioritise its own training runs without competing for third-party cloud capacity.
The timing of the release is notable. OpenAI's GPT-6 family launched in early 2026, and Anthropic's Fable 5.1 followed in mid-year. Meta's October release puts it roughly six months behind the frontier leaders, a gap that is narrower than the year-plus lag the company faced in previous generations. Whether that compressed timeline reflects improvements in Meta's internal processes or simply the maturation of the underlying scaling laws remains an open question.
Pricing, Access, and the Code Subscriber Wedge
The decision to gate Wonder Full behind a Muse Code subscription, rather than offering it through the API, signals a strategic bet on developer lock-in. Muse Code is Meta's GitHub Copilot competitor, and by reserving the most capable model for subscribers, Meta is effectively creating a two-tier inference market: general-purpose API access for Wonder, and premium capabilities for developers embedded in Meta's toolchain.
This mirrors strategies employed by OpenAI with GPT-6 Astra (ChatGPT Plus exclusive at launch) and Anthropic with Opus 5.5 (tiered access through Claude Pro). The logic is straightforward: frontier models are expensive to serve, and subscription revenue provides a more predictable margin than pay-per-token API usage, especially when dealing with long-context or memory-intensive workloads.
For developers evaluating Wonder, the $4/$20 pricing sits in the middle of the current frontier range. GPT-6 Sol costs approximately $3/$15, while Opus 5.5 runs $5/$25. The question is whether Wonder's memory capabilities justify the premium over Sol, particularly for use cases that do not require extended context retention.
What the Benchmarks Do Not Tell You
Meta's model card claims Wonder and Wonder Full achieve "comparable" scores to Fable 5.1 and GPT-6 Astra on standard benchmarks, but the company has not released a full technical paper or independent third-party evaluations. In the absence of that detail, the industry will rely on community testing over the coming weeks to validate Meta's claims.
Historically, Meta's benchmark reporting has been accurate but selective. The company tends to highlight metrics where its models perform well, such as MemoryBench in this case, while downplaying areas of weakness. For instance, Meta did not publish Wonder's performance on MMLU-Pro, HumanEval, or other widely tracked reasoning and coding benchmarks, suggesting the model may lag on those tasks.
The emphasis on memory also raises questions about inference cost. Maintaining state across sessions requires either fine-tuning per user or extremely large context windows, both of which drive up serving costs. If Wonder's memory features rely on expensive context retention, the $4/$20 pricing may not be sustainable at scale, and Meta may eventually need to raise prices or restrict usage.
The Restructure Dividend
The Wonder release is the first major frontier launch since Alexandr Wang took operational control of Meta's AI division. Wang, who built Scale AI into the dominant data labelling platform for large language models, was brought in to streamline Meta's notoriously fragmented AI efforts. His restructure consolidated research teams, centralised compute allocation, and imposed tighter release schedules.
The results are starting to show. Meta shipped Muse Spark in March, Muse agent in June, and now Wonder in October, a cadence that is faster than the company's historical pace. Whether that velocity can be sustained, and whether it translates into market share gains against OpenAI and Anthropic, will depend on execution over the next twelve months.
For now, Wonder represents a credible entry into the frontier tier, but not a breakthrough. The model's memory features are intriguing, but they address a relatively narrow use case compared to the general-purpose reasoning improvements that have driven GPT and Fable adoption. Meta is betting that long-term context retention will become the next battleground in AI assistants. If that bet pays off, Wonder could define the next phase of competition. If not, it risks being a well-engineered solution to a problem most users do not yet have.