China's AI Systems Now Generate More Data Than They Were Trained On
A government report marks the point where inference workloads eclipse training volumes, signalling widespread deployment across the world's second-largest AI market.
The Crossover Point
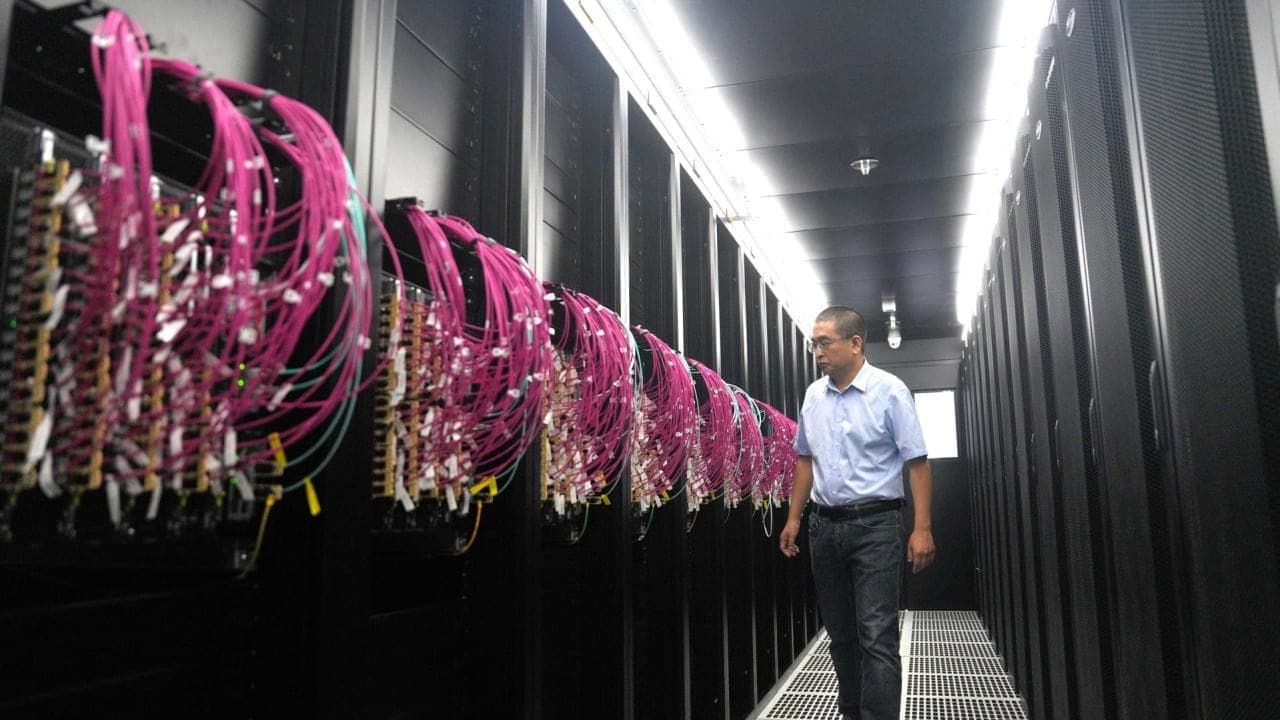
China's artificial intelligence infrastructure has reached a milestone that speaks less to laboratory breakthroughs and more to industrial momentum. Inference workloads generated by deployed AI systems across the country now exceed the volume of data used to train those models in the first place, according to figures released over the weekend by the China Centre for Information Industry Development, an arm of the Ministry of Industry and Information Technology.
The shift marks a turning point in how compute resources are allocated. For years, training large language models and vision systems consumed the lion's share of GPU cycles and network bandwidth. The new data suggests that the centre of gravity has moved downstream, toward the daily operation of models already in production, serving queries from enterprise customers, government platforms, and consumer applications.
At Opentechwire, we've tracked similar transitions in South Korea and Singapore over the past eighteen months, where inference clusters began outpacing training infrastructure investment by mid-2025. China's crossover arrives later than those markets, but at a scale that dwarfs them. The sheer volume of inference traffic reflects not just technical maturity but organisational adoption: models are no longer confined to pilot programmes or research labs.
What Inference Volume Reveals
The ratio of inference to training data is a proxy for deployment density. Training a frontier model might consume petabytes of text, images, and structured data over weeks or months. Once deployed, however, that same model can process vastly larger volumes of user queries, document analysis tasks, or real-time recommendations, day after day, across thousands of endpoints.
When inference surpasses training, it typically means two things. First, organisations have moved beyond experimentation. They are running models in production environments where uptime, latency, and cost per query matter more than parameter count. Second, the installed base of models is broad enough that aggregate inference demand outstrips the episodic spikes of training new versions.
The official data cited in the CCID report does not break down inference by sector, but parallel trends across the region offer clues. In retail and logistics, models handle product recommendations, inventory forecasting, and route optimisation at transactional scale. In finance, credit scoring and fraud detection systems query models millions of times per day. In manufacturing, quality control vision systems process camera feeds in real time on factory floors.
Each of these use cases generates inference requests that add up quickly. A single e-commerce platform can log more inference calls in a week than the training corpus it originally used to fine-tune its recommendation engine.
Infrastructure Implications
The shift from training-heavy to inference-heavy workloads reshapes the economics and architecture of AI infrastructure. Training favours high-end accelerators with maximum memory bandwidth and interconnect speed, often clustered in centralised data centres. Inference, by contrast, benefits from distribution: lower-latency chips deployed closer to users, edge nodes in regional hubs, and aggressive model compression to reduce cost per query.
China's hyperscale cloud providers have been building out inference-optimised infrastructure for the past two years, investing in custom ASICs and software stacks designed to serve models efficiently rather than train them quickly. The volume crossover validates that bet. It also underscores a strategic calculation: in a market where access to the latest Nvidia training chips remains constrained by export controls, scaling inference on domestically available hardware offers a path to growth that does not depend on frontier training runs.
The report's timing is notable. It arrives as Beijing continues to emphasise "new productive forces" in industrial policy, a phrase that encompasses AI deployment in traditional sectors. The message is clear: the value of AI lies not in the headline parameter counts of foundation models but in the cumulative output of systems already at work.
Regional Context
China is not alone in crossing this threshold, but the speed and scale are distinctive. Japan's inference-to-training ratio tipped in early 2026, driven largely by enterprise automation in manufacturing and logistics. India's market remains training-heavy, reflecting a younger AI ecosystem still focused on model development and research partnerships.
The contrast with the United States is instructive. American cloud providers crossed the inference threshold in late 2024, buoyed by widespread adoption of generative AI tools in knowledge work and customer service. China's later crossover reflects both the maturity curve of its domestic model landscape and the time required to integrate AI into state-owned enterprises and regulated industries, where procurement cycles are longer and deployment standards more conservative.
What China shares with other markets is the infrastructure challenge that follows. Inference at scale demands not just compute but orchestration: managing model versions, routing requests to the right hardware, and optimising cost without sacrificing performance. The next phase of competition will be less about who can train the largest model and more about who can serve the most queries per dollar.
The Deployment Agenda
The CCID report does not offer a road map, but it reflects priorities already visible in Chinese industrial policy. Provincial governments have launched procurement programmes for AI services, favouring vendors with proven inference capacity. State-owned banks and telecommunications operators have begun consolidating inference workloads onto shared platforms, seeking economies of scale.
The emphasis on inference also aligns with export control realities. Training a competitive frontier model requires access to the latest high-bandwidth accelerators, a supply chain that remains restricted. Inference, however, can run on a wider range of hardware, including older-generation chips and custom silicon designed for specific tasks. By shifting the centre of gravity toward deployment, China's AI sector plays to strengths it controls rather than constraints it cannot.
At the same time, the milestone raises questions about model diversity. High inference volumes can reflect either a broad ecosystem of specialised models or the dominance of a few general-purpose platforms serving a wide range of tasks. The report does not distinguish between these scenarios, but the answer will shape the competitive landscape. If inference is concentrated in a handful of large models, the market favours incumbents with scale. If it is distributed across many task-specific systems, the opportunity set remains open.
What Comes Next
The crossover from training to inference is not a finish line. It marks the beginning of a different set of challenges: managing inference costs as query volumes grow, maintaining model performance as data distributions shift, and integrating AI outputs into business processes that were not designed for probabilistic systems.
China's AI infrastructure is now optimised for a deployment-first environment. The question is whether the installed base of models can deliver the productivity gains that justify the investment. Inference volume is a measure of activity, not impact. The next set of benchmarks will need to capture outcomes: cost savings, revenue growth, and operational improvements that show up in enterprise balance sheets and government service metrics.
For now, the data point is a signal. The era of training-dominated AI spending in China has ended. What follows will be defined by how well deployed models perform, how efficiently they run, and how widely their benefits extend beyond the technology sector itself.