Inside Vals' Plan to Fix AI Benchmarking Before It Becomes Meaningless
A two-year-old startup has raised $40 million from Andreessen Horowitz to replace outdated tests with task-based evaluations that measure what models can actually do in law, finance, and security.
The Benchmark Problem Nobody Talks About
The AI industry has a measurement crisis. Companies routinely tout benchmark scores to justify valuations, win enterprise contracts, and distinguish themselves in an increasingly crowded field. Yet many of these scores reflect performance on tests that were designed for an earlier generation of models, and whose questions have been circulating online long enough for training datasets to absorb them. The result is a benchmarking ecosystem where high scores no longer guarantee real-world capability, and where the incentive structure rewards optimisation for known tests rather than genuine performance.
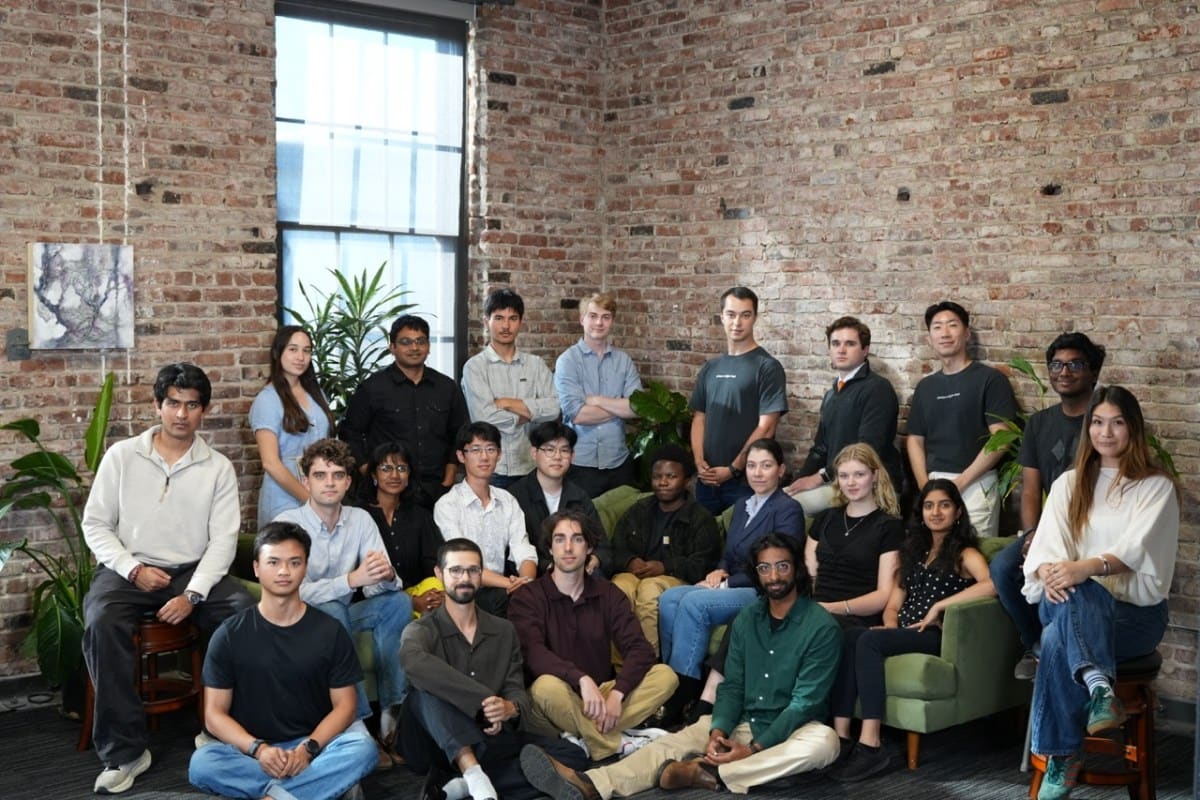
Vals, founded in 2024, has built its business around solving this asymmetry. The San Francisco-based startup secured a seed round from 8VC and Bloomberg Beta last year, then closed a $40 million Series A led by Andreessen Horowitz last month. The company now operates from a converted brewery building on Folsom Street, where its 25-person team designs proprietary evaluations that measure whether models can complete industry-specific tasks rather than answer abstract questions.
Rayan Krishnan, the 25-year-old co-founder who previously interned at Palantir and worked in Stanford's AI lab, frames the company's thesis around a gap he observed between frontier model capabilities and the tools used to assess them. Academic benchmarks, he argues, were falling behind the pace of model development, creating a validation void that needed filling with something more aligned to real deployment scenarios.
Task-Based Evaluation as a Commercial Product
Vals' core differentiation lies in its refusal to publish test materials. Where many benchmarking systems make their questions publicly available - allowing companies to train against them, either deliberately or through dataset contamination - Vals keeps its evaluations private. The startup also shifts focus from general knowledge assessments, such as bar exam simulations, to domain-specific task completion. Can a model draft a compliant securities filing? Can it identify vulnerabilities in production code? Can it apply the Geneva Convention to a hypothetical conflict scenario?
The company charges AI developers to run these evaluations, a revenue model that mirrors standardised testing in education. Krishnan draws the parallel to students paying the College Board for SAT access, arguing that companies need measurement infrastructure to troubleshoot models and track improvement over time. For enterprises evaluating which model to license, Vals' reports are becoming a procurement input, particularly as the startup expands into evaluations for mental health, cybersecurity, biosecurity, and even recursive self-improvement - the capacity of a model to iteratively enhance its own performance.
According to Vals, its revenue has grown eightfold over the past year. The team, which stood at eight people in January, has tripled to 25, with plans to add another 10 to 15 employees and relocate to a larger office. The startup also launched a programme targeting federal agencies, positioning its evaluations as a tool for public-sector AI adoption where accountability and auditability matter more than leaderboard rankings.
The Trust Infrastructure Thesis
Krishnan's longer-term vision hinges on benchmarking becoming embedded in the financial and regulatory architecture of the AI industry. As companies such as Anthropic prepare to go public - and as AI infrastructure becomes a larger share of enterprise IT budgets - he expects evaluation reports to feature in investor filings, procurement processes, and compliance documentation. In this framing, Vals is not simply a testing service but a trust layer: a third party that can verify claims before they reach customers, regulators, or shareholders.
The analogy to financial auditing is implicit but clear. Just as publicly traded companies submit to external audits to assure investors, AI companies may eventually need independent evaluation to assure buyers that a model performs as advertised. Vals is positioning itself to be that auditor, with proprietary test suites that cannot be gamed through training and a focus on negative outcomes - what happens if a model is deployed without sufficient guardrails - as well as positive capabilities.
This approach raises questions about access and standardisation. If Vals' tests remain proprietary, who decides what constitutes a fair evaluation? How do customers compare scores across different benchmarking providers? And does the pay-to-play model create conflicts of interest, where a vendor might soften assessments to retain clients? Krishnan's answer is that the alternative - publicly available tests that can be gamed - is worse, and that market pressure will discipline any provider that loses credibility.
Benchmarking as a Bottleneck or Catalyst
The broader debate around AI evaluation centres on whether benchmarks accelerate or distort progress. On one hand, well-designed tests create common standards, reduce information asymmetry, and give developers clear targets for improvement. On the other, they risk becoming Goodhart's Law in action: once a measure becomes a target, it ceases to be a good measure. Companies optimise for benchmark performance rather than real-world utility, and the industry converges on a narrow set of capabilities that happen to be easily testable.
Vals' task-based methodology attempts to sidestep this trap by tying evaluations to real workflows in law, finance, and security. But it also introduces new dependencies. If enterprises begin to rely on Vals' scores for procurement decisions, the startup effectively gains gatekeeping power over which models get adopted. If federal agencies use Vals to vet AI systems for deployment, the company becomes part of the regulatory apparatus, with all the scrutiny and responsibility that entails.
At Opentechwire, we've tracked the evolution of AI benchmarking from academic leaderboards to commercial infrastructure. The shift from open datasets such as GLUE and SuperGLUE to proprietary evaluation suites reflects a maturation of the market, but it also fragments the measurement landscape. Where once a single leaderboard could shape industry perception, companies now face a proliferation of competing benchmarks, each with its own methodology and blind spots. Vals' growth suggests that demand for independent, task-oriented evaluation is real, but it also underscores the challenge of building consensus around what "good" AI performance means in the first place.
What Comes After the Series A
With $40 million in fresh capital, Vals faces the operational challenge of scaling its evaluation capabilities without diluting rigour. The company is expanding into new domains - mental health, biosecurity, law of armed conflict - that require deep subject-matter expertise and careful test design. Hiring the right mix of AI researchers, domain specialists, and operations staff will determine whether Vals can maintain quality as it grows, or whether it becomes another vendor selling scores that clients learn to optimise for.
The startup's federal programme adds another layer of complexity. Government procurement moves slowly, requires extensive documentation, and often demands customisation that does not scale easily. But it also offers a path to legitimacy: if Vals can establish itself as the benchmarking standard for US agencies, that credibility will carry weight in enterprise sales and international markets.
Krishnan's bet is that AI companies will eventually need third-party validation the same way pharmaceutical companies need clinical trials and accounting firms need audits. Whether Vals becomes that validator, or whether the industry converges on a different model - open-source evaluation frameworks, industry consortia, regulatory mandates - remains an open question. For now, the startup has capital, momentum, and a clear thesis about where the market is headed. The harder part will be proving that its benchmarks measure what actually matters, rather than what is easiest to sell.