Unsiloed AI Raises $7.5 Million to Parse Complex Documents for Enterprise Automation
San Francisco startup addresses the accuracy gap in document processing as businesses deploy AI agents across finance, legal, and healthcare workflows
The Document Problem in Agent Workflows
Enterprise automation hits a stubborn obstacle long before most AI agents reach production: the formatted document. Balance sheets with nested tables, legal contracts spanning dozens of pages, medical records mixing narrative and structured data - these artefacts resist the probabilistic nature of language models, yet they remain central to workflows in banking, law, and healthcare.
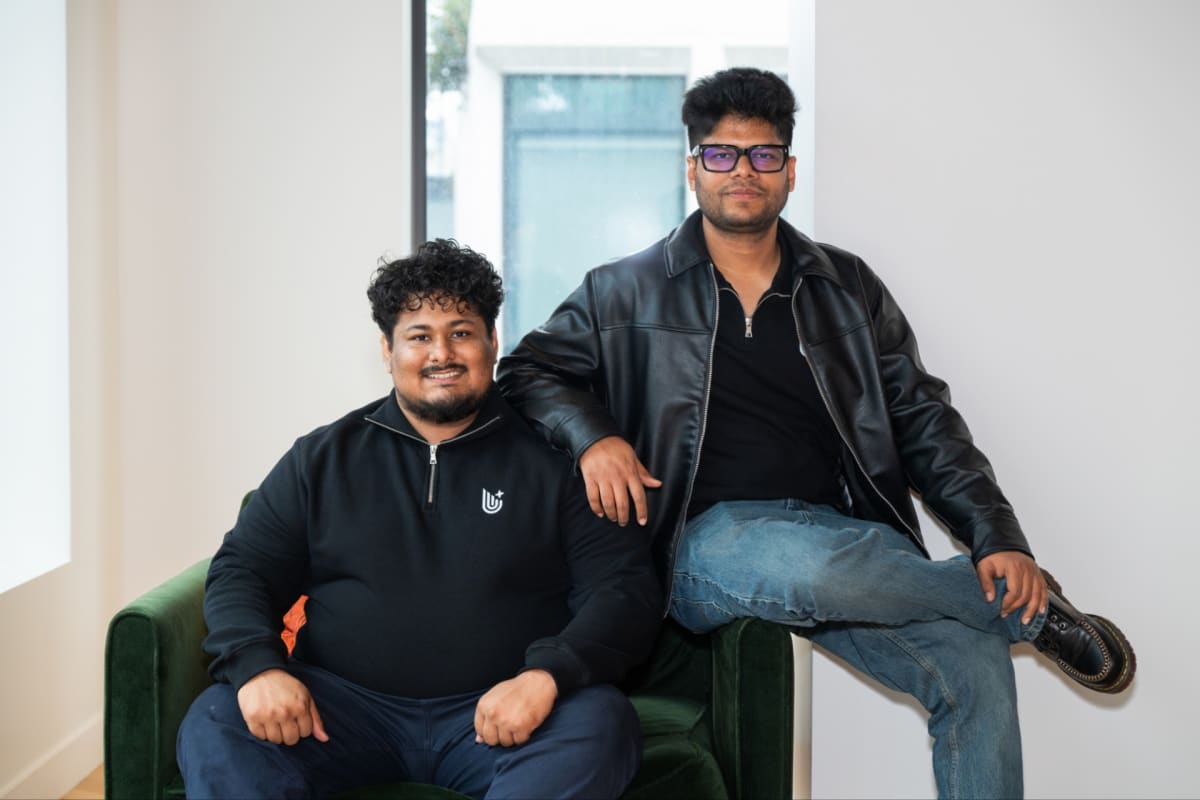
Unsiloed AI closed a $7.5 million seed round led by Felicis to build software that extracts information from such documents with verifiable accuracy. Y Combinator, Orange Collective, and Uncorrelated Ventures joined the financing, alongside angel investors Aarthi Ramamurthy and Beth Turner.
The company's thesis rests on a straightforward observation: businesses will deploy agents at scale only when the systems can handle the margin of error that matters in their domain. A retail chatbot might tolerate a misread product code; a bank processing loan applications cannot afford a transposed figure in a balance sheet.
Architecture Built for Precision Over Speed
Co-founders Aman Mishra and Adnan Abbas, both graduates of the Indian Institute of Technology Kharagpur, spent time before Y Combinator's autumn 2025 cohort developing what they describe as a dual-stream vision architecture. The system processes text tokens and image tokens in separate pipelines, then applies compute selectively to regions flagged by heat map-based chunking.
The approach directs processing power toward elements that carry the highest information density - numerical tables, charts, footnotes - rather than treating every paragraph uniformly. A specialised decoder layer then interprets terminology in context, distinguishing between industry-specific uses of the same term.
Mishra frames the design choice as a response to the inherent limitations of probabilistic models. Language models generate output by predicting the next token; that mechanism introduces variance, and variance in a financial figure or a legal clause can cascade into costly downstream errors. The dual-stream design aims to constrain that variance at the parsing stage, before the extracted data enters an agent's reasoning loop.
The system also returns provenance metadata for each extracted field, mapping it back to the source document. That traceability allows compliance teams or auditors to verify outputs rather than accept them on faith - a requirement in sectors where regulatory frameworks demand audit trails.
Early Traction in Regulated Verticals
Unsiloed has signed customers in finance, legal services, and healthcare, according to Mishra. One bank uses the platform to process loan and credit documents; a law firm deployed the software on-premises to handle contracts and archived case files. Voice AI startup Bolna AI ingests knowledge bases through Unsiloed to build conversational agents.
The customer base, though small, reflects the startup's focus on sectors where document accuracy carries direct liability. Banks face regulatory penalties for misreported figures; law firms risk malpractice claims if contract terms are misinterpreted; hospitals must maintain precise patient records under data protection and safety rules.
That focus also shapes Unsiloed's go-to-market strategy. Rather than targeting broad horizontal adoption, the company is building reference implementations in verticals where the cost of error is quantifiable. A single misread clause in a commercial lease can trigger disputes worth tens of thousands of dollars; a transposed lab result in a patient file can delay treatment.
The challenge for Unsiloed lies in converting those high-stakes use cases into repeatable sales. Regulated industries move slowly, and procurement cycles often stretch across quarters. The startup will need to demonstrate not only technical superiority but also integration ease and compliance with sector-specific standards - ISO certifications, SOC 2 attestations, HIPAA alignment in the United States, similar frameworks elsewhere.
Competitive Landscape and Differentiation Claims
Unsiloed enters a market already populated by document-processing specialists Reducto and Unstructured, as well as enterprise offerings from Microsoft Azure Document Intelligence and Amazon Textract. General-purpose models from OpenAI, Anthropic, and Google also handle document extraction, giving enterprises the option to build in-house pipelines.
Mishra argues that Unsiloed's dual-stream architecture and heat map chunking deliver higher accuracy on complex layouts. The startup shared a technical brief describing tests on 542 financial documents supplied by an enterprise customer. Across roughly 84,000 extracted data points, Unsiloed recorded 99.78 per cent accuracy, comparing favourably against major AI models, Microsoft's Azure service, and the customer's internal tool. Those results have not been independently audited.
On olmOCR-Bench, a public benchmark developed by Allen AI covering 1,403 PDF pages, Unsiloed scored 88.0. The startup's own testing put Reducto's agentic system at 66.0 and Unstructured at 39.9 on the same benchmark. The test set includes tables, mathematical expressions, scanned documents, and multi-column layouts.
Benchmark performance, however, offers only partial insight. Real-world accuracy depends on document variety, edge cases, and the cost of false positives versus false negatives in a given workflow. A tool optimised for financial tables may struggle with handwritten annotations in legal discovery; a system trained on English-language contracts may falter on multilingual documents common in cross-border transactions.
Pricing and Unit Economics
Unsiloed charges one cent per page. That pricing model positions the service below the cost of manual data entry - often several dollars per page for complex documents - but above the marginal cost of running general-purpose models in-house. The economic case depends on the value of accuracy gains and the labour saved in verification.
Mishra contends that selective compute allocation keeps costs low. By concentrating processing power on high-information regions rather than applying uniform treatment, the system reduces inference expense per page. That claim will face scrutiny as the startup scales; inference costs for vision models remain higher than for text-only workloads, and enterprise customers will compare Unsiloed's pricing against both manual processes and alternative automation tools.
The pricing structure also reflects a broader tension in enterprise AI: customers want predictable costs, but model providers face variable compute expenses tied to document complexity. Flat per-page pricing shifts risk onto Unsiloed; a surge in unusually complex documents could compress margins unless the heat map chunking delivers the efficiency gains the company projects.
Funding Deployment and Hiring Plans
The $7.5 million seed will fund hiring in research and engineering, expansion of the sales team, and development of proprietary training datasets. The company currently employs seven people.
Hiring in a competitive San Francisco talent market will test the startup's ability to attract specialists in computer vision, document understanding, and enterprise sales. Research roles demand expertise in multimodal architectures and OCR systems; sales roles require familiarity with procurement processes in regulated industries. Both skill sets command premium compensation.
Building proprietary datasets presents its own challenges. High-quality training data for document parsing requires not only raw documents but also ground-truth annotations - a labour-intensive process. Unsiloed will need to secure data partnerships with enterprises willing to share anonymised documents, or invest in annotation infrastructure. Data licensing and privacy compliance add further complexity, particularly when handling documents from healthcare or legal contexts.
The Agent Integration Question
Unsiloed positions itself as infrastructure for AI agents, but the agent ecosystem remains fragmented. Different agent frameworks - LangChain, AutoGPT, Microsoft's Semantic Kernel, proprietary enterprise stacks - handle document ingestion in varying ways. Unsiloed must either build connectors for each framework or persuade customers to adopt its API as a standard preprocessing layer.
The integration question extends to deployment models. Some enterprises will accept cloud-based document processing; others, particularly in legal and healthcare, require on-premises or private-cloud deployments. Supporting multiple deployment modes increases engineering overhead and complicates the startup's operational model.
As agent capabilities mature, the value proposition for specialised document parsing may shift. If future generations of multimodal models achieve near-perfect accuracy on complex layouts, the need for a dedicated preprocessing layer diminishes. Unsiloed's durability depends on whether document understanding remains a distinct technical problem or converges into general-purpose model capabilities.
What Comes Next
The seed round gives Unsiloed runway to prove that high-accuracy document parsing commands a premium in enterprise budgets. The next twelve months will reveal whether regulated industries adopt the platform at a pace that justifies venture-scale returns, or whether the sales cycle and integration complexity slow growth below investor expectations.
For enterprises evaluating the platform, the decision hinges on a cost-benefit calculation: does the accuracy gain over existing tools - whether in-house scripts, Azure Document Intelligence, or general-purpose models - justify the per-page fee and the integration effort? In sectors where a single parsing error can trigger regulatory fines or litigation, the answer may be yes. In less-regulated contexts, the case is harder to make.
Felicis's backing signals confidence that document understanding remains a bottleneck worth solving with specialised infrastructure. Whether that bottleneck persists as foundation models improve, or narrows into a niche problem, will determine the scale of the opportunity Unsiloed is chasing.