Recursive's Flint Runs on a Laptop and Was Built by Its Own AI Research System
The startup's first public model tests whether machines can design better machines, bringing recursive self-improvement from theory into practice on consumer hardware.
A Model Built by Machines
Recursive shipped its first model on 21 October 2026, and the release doubles as a proof-of-concept. Flint is a coding assistant small enough to run on consumer laptops, but its real significance lies in how it came to exist: the startup says nearly every stage of development - pre-training, post-training, inference optimisation - relied on an automated research system called the Eureka Machine. A team of fewer than a dozen people brought Flint from concept to release in under four months, a timeline the company attributes to machine-led research.
The model is free to download under the Apache 2.0 licence. It processes code locally, which means developers keep their work offline and avoid per-token cloud fees. For a segment of the market that values privacy and cost predictability over raw capability, that trade-off matters.
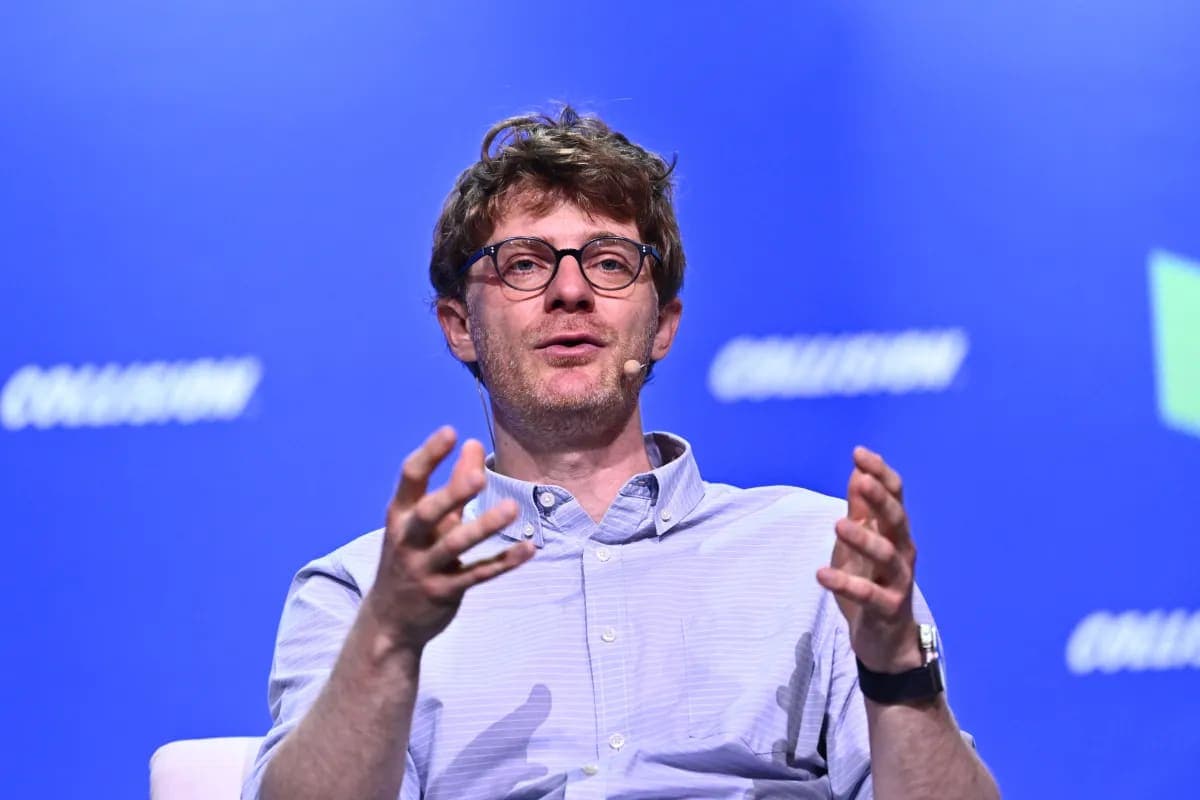
Recursive emerged from stealth in May 2026 with USD 650 million in backing at a USD 4.65 billion valuation. GV, Nvidia, and AMD Ventures are among the investors. Richard Socher, formerly chief scientist at Salesforce, leads the company. The name itself signals intent: Recursive is building systems that improve themselves, and Flint is the first public artefact of that ambition.
Mixture-of-Experts on 48GB of Memory
Flint is a mixture-of-experts architecture, activating only 2.5 billion parameters out of a total 40 billion for any given task. That selective activation keeps memory footprint and latency low. On a MacBook Pro equipped with Apple's M4 Pro chip, the model generated approximately 131 tokens per second in the company's internal tests - roughly double the throughput of Google's Gemma 4 and Nvidia's Nemotron 3.5 Lightning on the same hardware. On Nvidia's RTX Spark, generation exceeded 150 tokens per second.
The architecture stands in contrast to models designed for maximum capability. Meta released Muse Spark Open last week, an open model for Macs that deploys 816 billion parameters and requires at least one terabyte of memory. Flint targets the opposite end: developers who need a capable assistant on standard hardware, not a research cluster.
On SWE-Bench Verified, a benchmark measuring how well models fix real-world software bugs, Flint outperformed other models below 50 billion parameters. Across Recursive's own composite of six tests, only Alibaba's Qwen3.8 27B scored higher. The company acknowledged that Flint requires more structured prompts than commercial coding assistants - breaking large tasks into discrete steps improves results - but early user reports suggest the model handles typical development workflows reliably.
Will Knight at Wired tested Flint on a Mac with 48 gigabytes of memory, building a to-do list application and a web-scraping research tool. He noted that smaller coding models often stumble on error handling or lag behind proprietary services, but Flint completed each request without issue. That consistency, rather than frontier capability, appears to be the design goal.
The Eureka Machine as Co-Author
Recursive describes the Eureka Machine as an automated research system that generates hypotheses, runs experiments, and uses results to guide subsequent trials. According to the company's launch materials, the system contributed to nearly every phase of Flint's development. Specific contributions include a sparser model topology, low-bit quantisation that reduced model size by 71 per cent with minimal quality loss, and custom compute kernels tailored to inference speed.
The company did not disclose how many researcher-hours the Eureka Machine replaced, but the broader industry trend is clear. OpenAI reported in August 2026 that its AI agents were logging 3.1 workdays for every human researcher workday. Recursive told the press in June that its USD 410 million compute agreement with Amazon Web Services was "less about headcount and more about agent count." The implication: compute budget is scaling faster than hiring.
If the feedback loop works as designed, each model Recursive ships should make the Eureka Machine a more capable researcher, which in turn accelerates the next model. Socher told Wired the long-term objective is full recursive self-improvement, with human oversight and kill-switch authority retained. For now, that vision remains theoretical. Flint is a narrow test: a single-purpose model built with significant machine assistance, not an autonomous research lab.
Recursive Self-Improvement Leaves the Lab
The idea that AI can build better AI - and that better AI can build even better AI - has circulated in research circles for years, often under the label "recursive self-improvement." The concept carries both promise and risk. Optimists see a path to rapid capability gains; sceptics worry about systems that evolve faster than humans can evaluate them, or that optimise for objectives misaligned with intended use.
Recursive's approach is conservative by design. The Eureka Machine operates as a research assistant, not an autonomous agent. Humans review its proposals, validate experiments, and decide what ships. The company has not published detailed safety protocols, but the architecture - humans in the loop, narrow-domain models, local inference - suggests a deliberate effort to bound risk while testing the core hypothesis.
The release of Flint also tests a different hypothesis: whether the open-source community will adopt a model whose provenance includes significant machine authorship. Licensing under Apache 2.0 removes legal friction, and the ability to run offline on consumer hardware addresses a real pain point for developers working on proprietary code or in bandwidth-constrained environments. Early adoption signals will clarify whether "built by AI" is a selling point or a source of hesitation.
What Laptop Models Mean for the Stack
At Opentechwire, we've tracked the slow bifurcation of the AI model market. On one end, frontier labs race toward ever-larger parameter counts, longer context windows, and multimodal capabilities that demand data-centre-scale infrastructure. On the other, a cohort of startups and open-source projects targets edge deployment: models that run on phones, laptops, and embedded systems, trading capability for latency, privacy, and cost.
Flint sits firmly in the second category. Its 40-billion-parameter mixture-of-experts design is large enough to handle non-trivial coding tasks but small enough to fit in the memory of a well-equipped laptop. The performance benchmarks - 131 tokens per second on M4 Pro, over 150 on RTX Spark - suggest the model is production-ready for interactive use, not just a research demo.
The economic logic is straightforward. Cloud-based coding assistants charge per token or per seat, and costs accumulate quickly for teams that lean heavily on AI. A local model eliminates usage fees entirely, and the privacy guarantee - code never leaves the device - matters in regulated industries and competitive environments. If Flint's quality holds up in production, it becomes a credible alternative to subscription services for a subset of use cases.
The Eureka Machine adds a second-order question: if automated research systems can compress development timelines by an order of magnitude, what happens to the cost structure of model creation? Recursive's four-month sprint from concept to release, with a small team and heavy automation, suggests that the marginal cost of producing a capable model may be falling faster than the market expects. If that trend holds, the supply of specialised models - optimised for specific tasks, hardware, or privacy constraints - could expand rapidly.
The Next Loop
Recursive has not announced a timeline for its next model, but the company's thesis implies one is coming. Each release should improve the Eureka Machine's research capability, which should accelerate the next cycle. Whether that feedback loop compounds smoothly or hits diminishing returns will clarify over the next twelve to eighteen months.
For now, Flint is an existence proof. A small team, supported by automated research, built a competitive coding model in four months and released it under an open licence. The model runs on hardware most developers already own, and early users report it works. That combination - speed, cost, capability - will pressure both commercial coding assistants and other open-source projects to match or exceed it.
The question is not whether recursive self-improvement is possible in theory. Flint demonstrates it is possible in practice, at least in narrow domains with human oversight. The question is how far the loop can run before it hits a ceiling, and whether the systems that emerge from it remain aligned with the goals their creators intended.